docs(models): pin native cache and provider-state sources
This commit is contained in:
 Agent Workbench Dev
@@ -0,0 +1,15 @@
|
||||
# M2 第五批:原生缓存块与跨 Run 状态
|
||||
|
||||
2026-11-07,基线 `bdfeb29c85b3231bfd7bc24b8b5f49d40a3beebf`,干净工作树。承接 I14/I12 的冻结契约/当次 fetch 数据区分,完成 I09 原生块与工具缓存注解往返、I11 可配置会话/Task亲和与供应商状态绑定;I27/I28 CI 与 M3 单独续接。
|
||||
|
||||
1. [complete] 固定当前官方缓存/状态来源、复用 I15 原件并核SHA;8份来源清单见 tests/fixtures/native-cache-state/SOURCE.json 与 docs/NATIVE-CACHE-STATE-SOURCES.md。保留原丢注解、跨 Run 选线和状态身份缺项观察。Mnemo新结果只读登记,不作为本地验收。
|
||||
2. [in_progress] 保留 Messages 系统/用户/工具块及工具元数据;新增原生状态身份绑定和会话/Task/Run亲和,原用户设置、原快照、完整历史和未知原件不变。默认不偷偷添加缓存参数。
|
||||
3. [pending] 自有 HTTP JSON/SSE、混池、跨 Run、手选换模、修订/停用、停止/恢复/重启与所有工具结果不重放的确定性核对;上游原错误保留。
|
||||
4. [pending] 复用 Orven 模型中心/原生参数/上下文,完成真实保存恢复与宽窄网页/实际Electron验收、独立构建及逐输入/编译核对。
|
||||
5. [pending] 每阶段回顾、限定本地提交、最终证据清单与普通GitAtlas增量推送;旧封存根只读,原失败保留。
|
||||
|
||||
本批不委派、不读真实Key、不请求真实模型、不操作正式数据/配置/安装/重启,不续旧实验或用户工程。默认 unrestricted/passthrough/preserve 与持久 ask/auto/full 保持,不增加预算、上下文、输出、头或历史额度。工具权限以当前模式为准,不能把状态核对做成新增审批。缓存使用与供应商命中由原 usage 表示,保留 unknown;稳定前缀/亲和或相同指纹不是缓存收益证明。
|
||||
|
||||
W/AD/AE/AG 网络/unknown、重复读取普遍收益未证明、R/W v2真实排除边界与 Purge收益unknown保持。M3须真实 schema2迁移增量及新处理器产生结果后的回退,不能删新账本或直接移除逐表全等守卫。新证据只写 `.qa/m2-native-cache-state-2026-11-07/`。
|
||||
|
||||
接续保留原 source-1/source-2/source-3:首夹具错误、亲和来源断言失败和跨线状态整正文搜索失败仍待准确核对,不能把接续摘要当全绿。首次接续 mkdir 遇既有目录即停止;改为读取已有原件并使用新文件名,未覆盖证据。规划辅助只读路径/输出错误见 progress.md。
|
||||
@@ -0,0 +1,18 @@
|
||||
# M2 原生缓存与状态来源
|
||||
|
||||
2026-11-07,沿 `bdfeb29c` 接续 I09/I11。来源清单与正文 SHA 在 [SOURCE.json](../tests/fixtures/native-cache-state/SOURCE.json)。OpenAI 两篇完整页面复用本批已取得的官方 Docs 原件,Claude/DeepSeek 六篇复用 I15 的原正文,并逐 SHA 只读核对。接续时再次检索并打开 OpenAI 当前页面;新查询不覆盖先前原件或失败记录。
|
||||
|
||||
| 官方来源 | 本批采用范围 |
|
||||
| --- | --- |
|
||||
| [OpenAI conversation state](https://developers.openai.com/api/docs/guides/conversation-state) | 手动历史保留完整 output 数组、encrypted reasoning 与 assistant phase;不把仅有 response ID 当完整本地状态 |
|
||||
| [OpenAI prompt caching](https://developers.openai.com/api/docs/guides/prompt-caching) | 显式 content breakpoint、缓存 key/TTL/retention 独立透传;会话持续存在或前缀相同不保证命中 |
|
||||
| [Claude prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching) | 系统、消息、工具和工具结果的 cache_control、各块 TTL 及原生元数据保持原位置和顺序 |
|
||||
| [DeepSeek thinking](https://api-docs.deepseek.com/guides/thinking_mode) / [chat](https://api-docs.deepseek.com/api/create-chat-completion) | 同供应商范围内历史 assistant reasoning_content 完整保留;工具身份与原结果不重放 |
|
||||
| [DeepSeek cache](https://api-docs.deepseek.com/guides/kv_cache) | 缓存是上游行为,用原 usage 区分读写、未报告和 unknown |
|
||||
| [DeepSeek Responses](https://api-docs.deepseek.com/api/create-response.md) / [Messages](https://api-docs.deepseek.com/api/create-message.md) | 兼容接口原字段与原生状态分开,不按协议名称推断账户或供应商状态可互换 |
|
||||
|
||||
本地状态绑定记录实际使用的协议、请求 URL、型号、连接、凭据修订和有效请求头模板。它用于防止不透明历史在不同供应商范围误用,不认证缓存命中、模型身份或供应商兼容。普通生成参数和连接修订不等于凭据变更。旧无完整身份的状态保留原件和适用原因;常规文本与原工具调用可继续进入新请求。
|
||||
|
||||
新模型池默认会话保持;已有池沿原 Run 范围或关闭设置。用户可选择关闭、Run、Task、会话;手动选模和当前可用成员优先。跨 Run 亲和仅从已完成响应保存,诊断独立、未知请求不补成成功,不新增执行审批或 token 额度。
|
||||
|
||||
该来源核对及合成验证不能证明全球实际兼容、真实缓存收益、重复读取普遍改善或 Purge 收益。W/AD/AE/AG 的网络与 unknown、R/W v2 真实排除边界和原工程结果保持。
|
||||
@@ -1,5 +1,9 @@
|
||||
# 汇总发现
|
||||
|
||||
I09/I11接续决策:新池可默认会话保持,但旧池必须保留原Run范围;亲和只来自完成的真实响应且诊断路径独立。状态身份要核对实际请求路径/认证模板/版本头/型号/连接与凭据修订,改变原生普通生成参数不应误认凭据变化。状态无法适用时保留原件和原因、以常规文本/原调用构造新历史,不丢用户数据或自动重放工具。沿既有Orven池编辑与上下文/请求账本补真实控制和反馈,不另立页面。
|
||||
|
||||
I09/I11具体缺口:messagesBody重建文本和工具时丢非结构元数据,messagesHistory反向只取text并改变tool_result顺序;Messages/Responses原生助手状态只有endpoint/model绑定,缺实际请求版本/头/凭据范围;ModelHub sticky仅runId且重启不持久。需要按来源区分声明原生输入与不透明输出状态,当前状态不能跨供应商或凭据误用,原件不能因此丢弃。
|
||||
|
||||
原生状态核对新增源方参考:冻结预设/用户设置不等于actual standard会话采用,创建失败也不代表发过模型请求;输入估算/额外预留、压缩请求值与当次fetch数据必须分别核对。手机客户端期限/确认、服务端原任务成功、容量样本和被清理的分段证据不能互相补数或推定延迟段。新同步仅按源方报告登记,自己的透传/预算/身份和原未知结论不改变。
|
||||
|
||||
I14收尾复核:实际请求头观察必须绑定prepared fetch参数,原Run只能表示冻结设置;认证模板/独立Key引用、HTTP传输层补头和真实缓存命中证据分别说明。最终两端各8组验证通知正常滚动、原配置/密文/快照保持;871输入与29输出一致,176后端/209测试未变可复用原143/143。首身份验证误用TAP计数不是产品失败,原件保留后仅修验证器。源码交付不升级为真实供应商/自主工程/Purge收益通过;迁移增量与激活新处理器后的回退仍必须在M3证明。
|
||||
|
||||
@@ -1,5 +1,13 @@
|
||||
# 统一执行进度
|
||||
|
||||
I09/I11来源提交前git diff --check发现官方原文6处原有尾空白,来源字节/SHA保持不修剪;限定排除这两份官方正文后核对其它新增文件,后续另核Git blob原字节。不是产品检查失败,不改原来源来制造通过。
|
||||
|
||||
I09/I11阶段1来源复核完成:8份官方来源固定,SOURCE.json SHA ced3703c4afb174c5b939ffb3dd8572f22ff8e5f3fb8489f627f45880315b799;OpenAI完整Docs原件复用、Claude/DeepSeek六份逐SHA一致。接续再次打开当前两篇页面,原source-1/2/3失败保留,未重跑旧轮次;首次mkdir既有目录拒绝后改为新文件名写入。下一完成核心与用户连接保持范围及确定性边界,限定来源提交先行。
|
||||
|
||||
I09/I11接续复核(2026-11-07):沿bdfeb29c与已有未提交实现继续,planning catchup退出0且无补遗;已核AGENTS最新范围、采用计划、1.25计划与M2第五批计划。工作树含缓存块/身份/亲和核心及新测试,界面/来源封存/验证/提交尚未完成,不把简短接续摘要当验收。初次工作区根AGENTS不存在、过宽清单输出截断和假定CI目录不存在仅属只读调查错误;以后限定Agent-Workbench真实路径和输出范围。当前不委派/真实模型/Key/正式写入或重启,先核未提交输入再完成本批。
|
||||
|
||||
I09/I11阶段1开始:确认Messages转换丢系统/内容/工具缓存注解、亲和仅在Run;先保存当前OpenAI官方缓存/会话原件并复用I15 Claude/DeepSeek来源。planning catchup退出0/无补遗。初读误猜model-settings/model-native-settings文件名及PowerShell rg glob、过量来源结果输出仅属调查错误,后续改为真实文件列表/摘要输出。Mnemo新增准确报告/固定计划SHA与SSE partial只读资料另保留,不替代工作台验收;主任务继续。
|
||||
|
||||
Mnemo新调用方预算/状态同步已仅作只读登记:源方新版手机短3/3、900秒49/60发起/48客户端确认/p95约48.4/125新鲜采样仍失败;后查49服务端原任务成功不补成客户端窗口通过。47无网络响应与8离线/过期、分段事件清理后的延迟unknown分别保留。Harness2048→23→1/额外4096预留、修后2048与默认压缩65536/standard身份缺项分开;最新启动不能创建会话、0模型请求,14公开检查与独立边界失败分别记录,完整读改测/恢复未通过。固定旧计划SHA一致,明确reviews路径未找到。见[只读同步](docs/integration/MNEMO-CALLER-BUDGET-STATE-READONLY-2026-11-07.md)。工作台M2下一I09/I11/CI及M3顺序、开放默认/模型偏好/历史unknown保持,无真实模型/正式写入/委派或向源线程回复。
|
||||
|
||||
I14/I12本批阶段5完成:3207份1498866416字节已封存,manifest 3963ad9e02d3f62c1ae4d5fefcb59fdc0bcdc63682be1c72109542a60a2b408c;封存后全3207原件/871工作输入只读复核,35改变输入Git原字节与17当前文档链接通过,2个文档仅规范化行尾、产品输入未变。来源337d1bc9、核心f95507ab、界面26472d28及验收04c0556c已普通增量推送至既有GitAtlas feat/task-agreement-1.25,远端逐SHA一致。回执和完成接续最后另提交/推送再核对,不递归改回执。下一I09/I11缓存块/跨Run状态与I27/I28 CI,再M3真实schema2迁移增量/新处理器结果后回退;未发行/正式操作/真实模型,W/AD/AE/AG与重复读/R/W边界/Purge收益unknown保持。
|
||||
|
||||
@@ -1,5 +1,7 @@
|
||||
# Agent Workbench:核心代理能力研究与产品计划
|
||||
|
||||
M2第五批I09/I11已从bdfeb29c干净基线开始,见[原生缓存与状态计划](docs/M2-NATIVE-CACHE-STATE-PLAN.md):保留Messages块/工具注解及原生历史,配置会话/Task/Run亲和,状态按实际协议/地址/型号/凭据/版本身份核对;旧历史不改写,亲和/同指纹不当作缓存命中。随后CI及M3真实迁移增量/结果后回退。无真实模型/Key/正式写入/委派,历史unknown保持。
|
||||
|
||||
I14/I12阶段1–4完成:来源337d1bc9/核心f95507ab/界面26472d28,最后相关38/38和首候选143/143后端输入未变;最终871输入/29编译/74runtime、网页与实际Electron各8组/8图/三配色/1280及390,原metadata/cipher/存储快照exact、原I13/I15原件只读一致、自有进程/已知监听0。原失败与验收器错误保持。阶段5已完成封存/回顾/授权普通GitAtlas增量推送,源码与验收04c0556c远端逐SHA一致,回执及完成接续最后提交再核对,见[请求契约计划](docs/M2-REQUEST-CONTRACT-PLAN.md)和[验收](docs/QA-M2-REQUEST-CONTRACT.md)。下一I09/I11/CI、M3真实迁移增量及新处理器结果后回退,真实收益和Purge unknown保持。
|
||||
|
||||
M2第四批I14/I12从c7d1ad5e干净/远端一致基线开始,见[请求契约计划](docs/M2-REQUEST-CONTRACT-PLAN.md)。已实际取得官方OpenAI overview与Anthropic版本/头说明,先固定来源和旧/新默认分离,再请求版本/头/路径/快照与去凭据指纹。I15原根只读,0真实Key/模型/正式写入,不委派或重启;I09/I11/CI/M3与历史unknown保持。
|
||||
|
||||
+113
@@ -0,0 +1,113 @@
|
||||
{
|
||||
"schemaVersion": 1,
|
||||
"baseline": "bdfeb29c85b3231bfd7bc24b8b5f49d40a3beebf",
|
||||
"sources": [
|
||||
{
|
||||
"id": "openai-conversation-state",
|
||||
"provider": "openai",
|
||||
"url": "https://developers.openai.com/api/docs/guides/conversation-state",
|
||||
"checkedAt": "2026-11-07",
|
||||
"file": "sources/openai-conversation-state.md",
|
||||
"sha256": "8a62162c2ef6ff7e94dfdad5ba06f417f5a6c00ea6521e6466d462ff2fcd9b96",
|
||||
"bytes": 24788,
|
||||
"captureSha256": "df7776f8ac54a84b55cbc0d42bc2b80192428921d96b2e272d21754e2f3d5f8b",
|
||||
"representation": "official-docs-mcp-markdown-utf8",
|
||||
"scope": "complete-captured-page",
|
||||
"reusedReadOnly": true
|
||||
},
|
||||
{
|
||||
"id": "openai-prompt-caching",
|
||||
"provider": "openai",
|
||||
"url": "https://developers.openai.com/api/docs/guides/prompt-caching",
|
||||
"checkedAt": "2026-11-07",
|
||||
"file": "sources/openai-prompt-caching.md",
|
||||
"sha256": "01e57dacc2e5c0fb881b2d1909649983e9e327a5d6c17a98bb1183ee00e9d334",
|
||||
"bytes": 56425,
|
||||
"captureSha256": "ed312ad7e34d4de7f5861317481ae82b1bc3b9a1ae78d525c916a0d94231d522",
|
||||
"representation": "official-docs-mcp-markdown-utf8",
|
||||
"scope": "complete-captured-page",
|
||||
"reusedReadOnly": true
|
||||
},
|
||||
{
|
||||
"id": "claude-build-with-claude__prompt-caching",
|
||||
"provider": "anthropic",
|
||||
"url": "https://platform.claude.com/docs/en/build-with-claude/prompt-caching",
|
||||
"checkedAt": "2026-11-06",
|
||||
"sha256": "ff35232788f3f7fbd0f9aae002351567a9ea8e68e5b749069d96dab52882747d",
|
||||
"file": "../official-model-registry/sources/claude-build-with-claude-prompt-caching.md",
|
||||
"originalSha256": "ff35232788f3f7fbd0f9aae002351567a9ea8e68e5b749069d96dab52882747d",
|
||||
"representation": "extracted-official-markdown",
|
||||
"scope": "complete-captured-source",
|
||||
"bytes": 164465,
|
||||
"reusedReadOnly": true
|
||||
},
|
||||
{
|
||||
"id": "deepseek-create",
|
||||
"provider": "deepseek",
|
||||
"url": "https://api-docs.deepseek.com/api/create-chat-completion",
|
||||
"checkedAt": "2026-11-06",
|
||||
"sha256": "b43ca950bd04ae7f6f537b42e6cb729f543d942dcd848ec43ad4e9bfe059fe1f",
|
||||
"file": "../official-model-registry/sources/deepseek-create.body",
|
||||
"originalSha256": "b43ca950bd04ae7f6f537b42e6cb729f543d942dcd848ec43ad4e9bfe059fe1f",
|
||||
"representation": "received-html-bytes",
|
||||
"scope": "complete-captured-source",
|
||||
"bytes": 129498,
|
||||
"reusedReadOnly": true
|
||||
},
|
||||
{
|
||||
"id": "deepseek-thinking",
|
||||
"provider": "deepseek",
|
||||
"url": "https://api-docs.deepseek.com/guides/thinking_mode",
|
||||
"checkedAt": "2026-11-06",
|
||||
"sha256": "42151b5f86827bff663a61693080a61cdbf99074dee94af756c9fce855baa7cd",
|
||||
"file": "../official-model-registry/sources/deepseek-thinking.body",
|
||||
"originalSha256": "42151b5f86827bff663a61693080a61cdbf99074dee94af756c9fce855baa7cd",
|
||||
"representation": "received-html-bytes",
|
||||
"scope": "complete-captured-source",
|
||||
"bytes": 117778,
|
||||
"reusedReadOnly": true
|
||||
},
|
||||
{
|
||||
"id": "deepseek-cache",
|
||||
"provider": "deepseek",
|
||||
"url": "https://api-docs.deepseek.com/guides/kv_cache",
|
||||
"checkedAt": "2026-11-06",
|
||||
"sha256": "061c0c7055ceb96d0a522ae1829ff5f7126ff08f26af217643e371abb740a081",
|
||||
"file": "../official-model-registry/sources/deepseek-cache.body",
|
||||
"originalSha256": "061c0c7055ceb96d0a522ae1829ff5f7126ff08f26af217643e371abb740a081",
|
||||
"representation": "received-html-bytes",
|
||||
"scope": "complete-captured-source",
|
||||
"bytes": 35850,
|
||||
"reusedReadOnly": true
|
||||
},
|
||||
{
|
||||
"id": "deepseek-response",
|
||||
"provider": "deepseek",
|
||||
"url": "https://api-docs.deepseek.com/api/create-response.md",
|
||||
"checkedAt": "2026-11-07",
|
||||
"sha256": "5e56e45d25db47f2b6966bbb0b2471d324035c33f0c8f81eaaf8fc444e6869da",
|
||||
"file": "../official-model-registry/sources/deepseek-response.md",
|
||||
"originalSha256": "5e56e45d25db47f2b6966bbb0b2471d324035c33f0c8f81eaaf8fc444e6869da",
|
||||
"representation": "received-document-bytes",
|
||||
"scope": "complete-captured-source",
|
||||
"bytes": 33870,
|
||||
"reusedReadOnly": true
|
||||
},
|
||||
{
|
||||
"id": "deepseek-message",
|
||||
"provider": "deepseek",
|
||||
"url": "https://api-docs.deepseek.com/api/create-message.md",
|
||||
"checkedAt": "2026-11-07",
|
||||
"sha256": "46b31d10f429910bf93ea2166537fb803cd2f49f7c5b4ad2ee4f08257b2e17e8",
|
||||
"file": "../official-model-registry/sources/deepseek-message.md",
|
||||
"originalSha256": "46b31d10f429910bf93ea2166537fb803cd2f49f7c5b4ad2ee4f08257b2e17e8",
|
||||
"representation": "received-document-bytes",
|
||||
"scope": "complete-captured-source",
|
||||
"bytes": 51134,
|
||||
"reusedReadOnly": true
|
||||
}
|
||||
],
|
||||
"newRealModelRequests": 0,
|
||||
"previousEvidenceRootsWritten": 0,
|
||||
"scope": "request-block-fidelity-provider-state-and-affinity-contracts-not-live-cache-benefit"
|
||||
}
|
||||
@@ -0,0 +1,795 @@
|
||||
# Conversation state
|
||||
|
||||
OpenAI provides a few ways to manage conversation state, which is important for preserving information across multiple messages or turns in a conversation.
|
||||
|
||||
|
||||
When troubleshooting cases where GPT-5.5 treats an intermediate update as
|
||||
the final answer, verify your integration preserves the assistant message
|
||||
`phase` field correctly. See [Phase
|
||||
parameter](https://developers.openai.com/api/docs/guides/reasoning#phase-parameter) for details.
|
||||
|
||||
|
||||
## Manually manage conversation state
|
||||
|
||||
While each text generation request is independent and stateless, you can still implement **multi-turn conversations** by providing additional messages as parameters to your text generation request. Consider a knock-knock joke:
|
||||
|
||||
|
||||
|
||||
Manually construct a past conversation
|
||||
|
||||
```javascript
|
||||
import OpenAI from "openai";
|
||||
|
||||
const openai = new OpenAI();
|
||||
|
||||
const response = await openai.responses.create({
|
||||
model: "gpt-6-astra",
|
||||
input: [
|
||||
{ role: "user", content: "knock knock." },
|
||||
{ role: "assistant", content: "Who's there?" },
|
||||
{ role: "user", content: "Orange." },
|
||||
],
|
||||
});
|
||||
|
||||
console.log(response.output_text);
|
||||
```
|
||||
|
||||
```python
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI()
|
||||
|
||||
response = client.responses.create(
|
||||
model="gpt-6-astra",
|
||||
input=[
|
||||
{"role": "user", "content": "knock knock."},
|
||||
{"role": "assistant", "content": "Who's there?"},
|
||||
{"role": "user", "content": "Orange."},
|
||||
],
|
||||
)
|
||||
|
||||
print(response.output_text)
|
||||
```
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"fmt"
|
||||
|
||||
"github.com/openai/openai-go/v3"
|
||||
"github.com/openai/openai-go/v3/responses"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client := openai.NewClient()
|
||||
|
||||
response, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
|
||||
Model: "gpt-6-astra",
|
||||
Input: responses.ResponseNewParamsInputUnion{
|
||||
OfInputItemList: responses.ResponseInputParam{
|
||||
responses.ResponseInputItemParamOfMessage("Knock knock.", responses.EasyInputMessageRoleUser),
|
||||
responses.ResponseInputItemParamOfMessage("Who's there?", responses.EasyInputMessageRoleAssistant),
|
||||
responses.ResponseInputItemParamOfMessage("Orange.", responses.EasyInputMessageRoleUser),
|
||||
},
|
||||
},
|
||||
})
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
|
||||
fmt.Println(response.OutputText())
|
||||
}
|
||||
```
|
||||
|
||||
```java
|
||||
import com.openai.client.OpenAIClient;
|
||||
import com.openai.client.okhttp.OpenAIOkHttpClient;
|
||||
import com.openai.models.responses.EasyInputMessage;
|
||||
import com.openai.models.responses.ResponseCreateParams;
|
||||
import com.openai.models.responses.ResponseInputItem;
|
||||
import java.util.List;
|
||||
|
||||
ResponseCreateParams params =
|
||||
ResponseCreateParams.builder()
|
||||
.model("gpt-6-astra")
|
||||
.inputOfResponse(
|
||||
List.of(
|
||||
ResponseInputItem.ofEasyInputMessage(
|
||||
EasyInputMessage.builder()
|
||||
.role(EasyInputMessage.Role.USER)
|
||||
.content("Knock knock.")
|
||||
.build()),
|
||||
ResponseInputItem.ofEasyInputMessage(
|
||||
EasyInputMessage.builder()
|
||||
.role(EasyInputMessage.Role.ASSISTANT)
|
||||
.content("Who's there?")
|
||||
.build()),
|
||||
ResponseInputItem.ofEasyInputMessage(
|
||||
EasyInputMessage.builder()
|
||||
.role(EasyInputMessage.Role.USER)
|
||||
.content("Orange.")
|
||||
.build())))
|
||||
.build();
|
||||
|
||||
client.responses().create(params).output().stream()
|
||||
.flatMap(item -> item.message().stream())
|
||||
.flatMap(message -> message.content().stream())
|
||||
.flatMap(content -> content.outputText().stream())
|
||||
.forEach(text -> System.out.println(text.text()));
|
||||
```
|
||||
|
||||
```csharp
|
||||
using OpenAI.Responses;
|
||||
#pragma warning disable OPENAI001
|
||||
|
||||
string key = Environment.GetEnvironmentVariable("OPENAI_API_KEY")!;
|
||||
ResponsesClient client = new(key);
|
||||
|
||||
ResponseResult response = await client.CreateResponseAsync(
|
||||
"gpt-6-astra",
|
||||
[
|
||||
ResponseItem.CreateUserMessageItem("Knock knock."),
|
||||
ResponseItem.CreateAssistantMessageItem("Who's there?"),
|
||||
ResponseItem.CreateUserMessageItem("Orange."),
|
||||
]
|
||||
);
|
||||
|
||||
Console.WriteLine(response.GetOutputText());
|
||||
```
|
||||
|
||||
```ruby
|
||||
require "openai"
|
||||
|
||||
client = OpenAI::Client.new
|
||||
|
||||
response = client.responses.create(
|
||||
model: "gpt-6-astra",
|
||||
input: [
|
||||
{
|
||||
role: :user,
|
||||
content: "Knock knock."
|
||||
},
|
||||
{
|
||||
role: :assistant,
|
||||
content: "Who's there?"
|
||||
},
|
||||
{
|
||||
role: :user,
|
||||
content: "Orange."
|
||||
}
|
||||
]
|
||||
)
|
||||
|
||||
puts(response.output_text)
|
||||
```
|
||||
|
||||
|
||||
|
||||
By using alternating `user` and `assistant` messages, you capture the previous state of a conversation in one request to the model.
|
||||
|
||||
To manually share context across generated responses, include the model's previous response output as input, and append that input to your next request.
|
||||
|
||||
For stateless reasoning-model requests, preserve every item in the response's `output` array. The Responses API returns encrypted reasoning items by default. Replaying the complete output keeps reasoning items and assistant `phase` values intact. Models that support persisted reasoning can use `reasoning.context: "all_turns"` to render the available reasoning from earlier turns into the next sample. See [preserve reasoning across calls](https://developers.openai.com/api/docs/guides/reasoning#preserve-reasoning-across-calls).
|
||||
|
||||
In the following example, we ask the model to tell a joke, followed by a request for another joke. Appending previous responses to new requests in this way helps ensure conversations feel natural and retain the context of previous interactions.
|
||||
|
||||
|
||||
|
||||
|
||||
Manually manage conversation state with the Responses API.
|
||||
|
||||
```javascript
|
||||
import OpenAI from "openai";
|
||||
import { toResponseInputItems } from "openai/lib/responses/ResponseInputItems";
|
||||
|
||||
const openai = new OpenAI();
|
||||
|
||||
let history = [
|
||||
{
|
||||
role: "user",
|
||||
content: "tell me a joke",
|
||||
},
|
||||
];
|
||||
|
||||
const response = await openai.responses.create({
|
||||
model: "gpt-6-astra",
|
||||
input: history,
|
||||
store: false,
|
||||
});
|
||||
|
||||
console.log(response.output_text);
|
||||
|
||||
// Add replayable output items, including reasoning items, to the history
|
||||
history.push(...toResponseInputItems(response.output));
|
||||
|
||||
history.push({
|
||||
role: "user",
|
||||
content: "tell me another",
|
||||
});
|
||||
|
||||
const secondResponse = await openai.responses.create({
|
||||
model: "gpt-6-astra",
|
||||
input: history,
|
||||
store: false,
|
||||
});
|
||||
|
||||
console.log(secondResponse.output_text);
|
||||
```
|
||||
|
||||
```python
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI()
|
||||
|
||||
history = [{"role": "user", "content": "tell me a joke"}]
|
||||
|
||||
response = client.responses.create(
|
||||
model="gpt-6-astra",
|
||||
input=history,
|
||||
store=False,
|
||||
)
|
||||
|
||||
print(response.output_text)
|
||||
|
||||
# Add all response output items, including encrypted reasoning items, to the conversation
|
||||
history += response.output
|
||||
|
||||
history.append({"role": "user", "content": "tell me another"})
|
||||
|
||||
second_response = client.responses.create(
|
||||
model="gpt-6-astra",
|
||||
input=history,
|
||||
store=False,
|
||||
)
|
||||
|
||||
print(second_response.output_text)
|
||||
```
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"encoding/json"
|
||||
"fmt"
|
||||
|
||||
"github.com/openai/openai-go/v3"
|
||||
"github.com/openai/openai-go/v3/responses"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client := openai.NewClient()
|
||||
history := responses.ResponseInputParam{
|
||||
responses.ResponseInputItemParamOfMessage("tell me a joke", responses.EasyInputMessageRoleUser),
|
||||
}
|
||||
first, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
|
||||
Model: "gpt-6-astra",
|
||||
Input: responses.ResponseNewParamsInputUnion{OfInputItemList: history},
|
||||
Store: openai.Bool(false),
|
||||
})
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
fmt.Println(first.OutputText())
|
||||
|
||||
history = append(history, outputAsInput(first.Output)...)
|
||||
history = append(history, responses.ResponseInputItemParamOfMessage("tell me another", responses.EasyInputMessageRoleUser))
|
||||
second, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
|
||||
Model: "gpt-6-astra",
|
||||
Input: responses.ResponseNewParamsInputUnion{OfInputItemList: history},
|
||||
Store: openai.Bool(false),
|
||||
})
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
fmt.Println(second.OutputText())
|
||||
}
|
||||
|
||||
func outputAsInput(output []responses.ResponseOutputItemUnion) []responses.ResponseInputItemUnionParam {
|
||||
input := make([]responses.ResponseInputItemUnionParam, 0, len(output))
|
||||
for _, item := range output {
|
||||
var converted responses.ResponseInputItemUnion
|
||||
if err := json.Unmarshal([]byte(item.RawJSON()), &converted); err != nil {
|
||||
panic(err)
|
||||
}
|
||||
input = append(input, converted.ToParam())
|
||||
}
|
||||
return input
|
||||
}
|
||||
```
|
||||
|
||||
```java
|
||||
import com.openai.client.OpenAIClient;
|
||||
import com.openai.client.okhttp.OpenAIOkHttpClient;
|
||||
import com.openai.core.JsonValue;
|
||||
import com.openai.models.responses.EasyInputMessage;
|
||||
import com.openai.models.responses.ResponseCreateParams;
|
||||
import com.openai.models.responses.ResponseInputItem;
|
||||
import java.util.ArrayList;
|
||||
|
||||
var history = new ArrayList<ResponseInputItem>();
|
||||
history.add(
|
||||
ResponseInputItem.ofEasyInputMessage(
|
||||
EasyInputMessage.builder()
|
||||
.role(EasyInputMessage.Role.USER)
|
||||
.content("Tell me a joke.")
|
||||
.build()));
|
||||
|
||||
var first =
|
||||
client
|
||||
.responses()
|
||||
.create(
|
||||
ResponseCreateParams.builder()
|
||||
.model("gpt-6-astra")
|
||||
.inputOfResponse(history)
|
||||
.store(false)
|
||||
.build());
|
||||
first.output().stream()
|
||||
.flatMap(item -> item.message().stream())
|
||||
.flatMap(message -> message.content().stream())
|
||||
.flatMap(content -> content.outputText().stream())
|
||||
.forEach(text -> System.out.println(text.text()));
|
||||
first.output().stream()
|
||||
.map(item -> JsonValue.from(item).convert(ResponseInputItem.class))
|
||||
.forEach(history::add);
|
||||
history.add(
|
||||
ResponseInputItem.ofEasyInputMessage(
|
||||
EasyInputMessage.builder()
|
||||
.role(EasyInputMessage.Role.USER)
|
||||
.content("Tell me another.")
|
||||
.build()));
|
||||
|
||||
client
|
||||
.responses()
|
||||
.create(
|
||||
ResponseCreateParams.builder()
|
||||
.model("gpt-6-astra")
|
||||
.inputOfResponse(history)
|
||||
.store(false)
|
||||
.build())
|
||||
.output()
|
||||
.stream()
|
||||
.flatMap(item -> item.message().stream())
|
||||
.flatMap(message -> message.content().stream())
|
||||
.flatMap(content -> content.outputText().stream())
|
||||
.forEach(text -> System.out.println(text.text()));
|
||||
```
|
||||
|
||||
```csharp
|
||||
using OpenAI.Responses;
|
||||
#pragma warning disable OPENAI001
|
||||
|
||||
string key = Environment.GetEnvironmentVariable("OPENAI_API_KEY")!;
|
||||
ResponsesClient client = new(key);
|
||||
|
||||
List<ResponseItem> history =
|
||||
[
|
||||
ResponseItem.CreateUserMessageItem("Tell me a joke."),
|
||||
];
|
||||
|
||||
CreateResponseOptions options = new("gpt-6-astra", history)
|
||||
{
|
||||
StoredOutputEnabled = false,
|
||||
IncludedProperties =
|
||||
{
|
||||
IncludedResponseProperty.ReasoningEncryptedContent,
|
||||
},
|
||||
};
|
||||
ResponseResult first = await client.CreateResponseAsync(options);
|
||||
Console.WriteLine(first.GetOutputText());
|
||||
|
||||
history.AddRange(first.OutputItems);
|
||||
history.Add(ResponseItem.CreateUserMessageItem("Tell me another."));
|
||||
|
||||
options = new("gpt-6-astra", history)
|
||||
{
|
||||
StoredOutputEnabled = false,
|
||||
IncludedProperties =
|
||||
{
|
||||
IncludedResponseProperty.ReasoningEncryptedContent,
|
||||
},
|
||||
};
|
||||
ResponseResult second = await client.CreateResponseAsync(options);
|
||||
Console.WriteLine(second.GetOutputText());
|
||||
```
|
||||
|
||||
```ruby
|
||||
require "openai"
|
||||
|
||||
client = OpenAI::Client.new
|
||||
history = [
|
||||
{
|
||||
role: :user,
|
||||
content: "Tell me a joke."
|
||||
}
|
||||
]
|
||||
|
||||
first = client.responses.create(
|
||||
model: "gpt-6-astra",
|
||||
input: history,
|
||||
store: false
|
||||
)
|
||||
puts(first.output_text)
|
||||
|
||||
history.concat(first.output)
|
||||
history << {
|
||||
role: :user,
|
||||
content: "Tell me another."
|
||||
}
|
||||
|
||||
second = client.responses.create(
|
||||
model: "gpt-6-astra",
|
||||
input: history,
|
||||
store: false
|
||||
)
|
||||
puts(second.output_text)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## OpenAI APIs for conversation state
|
||||
|
||||
Our APIs make it easier to manage conversation state automatically, so you don't have to pass inputs manually with each turn of a conversation.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
### Using the Conversations API
|
||||
|
||||
The [Conversations API](https://developers.openai.com/api/reference/resources/conversations/methods/create) works with the [Responses API](https://developers.openai.com/api/reference/resources/responses/methods/create) to persist conversation state as a long-running object with its own durable identifier. After creating a conversation object, you can keep using it across sessions, devices, or jobs.
|
||||
|
||||
Conversations store items, which can be messages, tool calls, tool outputs, and other data.
|
||||
|
||||
Create a conversation
|
||||
|
||||
```javascript
|
||||
const conversation = await client.conversations.create();
|
||||
```
|
||||
|
||||
```python
|
||||
conversation = openai.conversations.create()
|
||||
```
|
||||
|
||||
```go
|
||||
conversation, err := client.Conversations.New(context.Background(), conversations.ConversationNewParams{})
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
```
|
||||
|
||||
```java
|
||||
import com.openai.client.OpenAIClient;
|
||||
import com.openai.client.okhttp.OpenAIOkHttpClient;
|
||||
|
||||
var conversation = client.conversations().create();
|
||||
|
||||
System.out.println(conversation.id());
|
||||
```
|
||||
|
||||
```ruby
|
||||
conversation = client.conversations.create
|
||||
```
|
||||
|
||||
|
||||
In a multi-turn interaction, you can pass the `conversation` into subsequent responses to persist state and share context across subsequent responses, rather than having to chain multiple response items together.
|
||||
|
||||
Manage conversation state with Conversations and Responses APIs
|
||||
|
||||
```javascript
|
||||
const response = await client.responses.create({
|
||||
model: "gpt-6-astra",
|
||||
input: [{ role: "user", content: "What are the five Ds of dodgeball?" }],
|
||||
conversation: conversation.id,
|
||||
});
|
||||
|
||||
console.log(response.output_text);
|
||||
```
|
||||
|
||||
```python
|
||||
response = openai.responses.create(
|
||||
model="gpt-6-astra",
|
||||
input=[{"role": "user", "content": "What are the 5 Ds of dodgeball?"}],
|
||||
conversation=conversation.id,
|
||||
)
|
||||
```
|
||||
|
||||
```go
|
||||
response, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
|
||||
Model: "gpt-6-astra",
|
||||
Conversation: responses.ResponseNewParamsConversationUnion{
|
||||
OfString: openai.String(conversation.ID),
|
||||
},
|
||||
Input: responses.ResponseNewParamsInputUnion{
|
||||
OfString: openai.String("What are the five Ds of dodgeball?"),
|
||||
},
|
||||
})
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
fmt.Println(response.OutputText())
|
||||
```
|
||||
|
||||
```java
|
||||
import com.openai.client.OpenAIClient;
|
||||
import com.openai.client.okhttp.OpenAIOkHttpClient;
|
||||
import com.openai.models.responses.ResponseCreateParams;
|
||||
|
||||
var conversation = client.conversations().create();
|
||||
|
||||
var response =
|
||||
client
|
||||
.responses()
|
||||
.create(
|
||||
ResponseCreateParams.builder()
|
||||
.model("gpt-6-astra")
|
||||
.conversation(conversation.id())
|
||||
.input("What are the five Ds of dodgeball?")
|
||||
.build());
|
||||
|
||||
response.output().stream()
|
||||
.flatMap(item -> item.message().stream())
|
||||
.flatMap(message -> message.content().stream())
|
||||
.flatMap(content -> content.outputText().stream())
|
||||
.forEach(text -> System.out.println(text.text()));
|
||||
```
|
||||
|
||||
```ruby
|
||||
response = client.responses.create(
|
||||
model: "gpt-6-astra",
|
||||
conversation: conversation.id,
|
||||
input: "What are the five Ds of dodgeball?"
|
||||
)
|
||||
|
||||
puts(response.output_text)
|
||||
```
|
||||
|
||||
|
||||
### Passing context from the previous response
|
||||
|
||||
Another way to manage conversation state is to share context across generated responses with the `previous_response_id` parameter. This parameter lets you chain responses and create a threaded conversation.
|
||||
|
||||
Chain responses across turns by passing the previous response ID
|
||||
|
||||
```javascript
|
||||
import OpenAI from "openai";
|
||||
|
||||
const openai = new OpenAI();
|
||||
|
||||
const response = await openai.responses.create({
|
||||
model: "gpt-6-astra",
|
||||
input: "tell me a joke",
|
||||
store: true,
|
||||
});
|
||||
|
||||
console.log(response.output_text);
|
||||
|
||||
const secondResponse = await openai.responses.create({
|
||||
model: "gpt-6-astra",
|
||||
previous_response_id: response.id,
|
||||
input: [{ role: "user", content: "explain why this is funny." }],
|
||||
store: true,
|
||||
});
|
||||
|
||||
console.log(secondResponse.output_text);
|
||||
```
|
||||
|
||||
```python
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI()
|
||||
|
||||
response = client.responses.create(
|
||||
model="gpt-6-astra",
|
||||
input="tell me a joke",
|
||||
)
|
||||
print(response.output_text)
|
||||
|
||||
second_response = client.responses.create(
|
||||
model="gpt-6-astra",
|
||||
previous_response_id=response.id,
|
||||
input=[{"role": "user", "content": "explain why this is funny."}],
|
||||
)
|
||||
print(second_response.output_text)
|
||||
```
|
||||
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"context"
|
||||
"fmt"
|
||||
|
||||
"github.com/openai/openai-go/v3"
|
||||
"github.com/openai/openai-go/v3/responses"
|
||||
)
|
||||
|
||||
func main() {
|
||||
client := openai.NewClient()
|
||||
|
||||
first, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
|
||||
Model: "gpt-6-astra",
|
||||
Input: responses.ResponseNewParamsInputUnion{
|
||||
OfString: openai.String("Tell me a joke."),
|
||||
},
|
||||
})
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
fmt.Println(first.OutputText())
|
||||
|
||||
second, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
|
||||
Model: "gpt-6-astra",
|
||||
PreviousResponseID: openai.String(first.ID),
|
||||
Input: responses.ResponseNewParamsInputUnion{
|
||||
OfString: openai.String("Explain why this is funny."),
|
||||
},
|
||||
})
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
fmt.Println(second.OutputText())
|
||||
}
|
||||
```
|
||||
|
||||
```java
|
||||
import com.openai.client.OpenAIClient;
|
||||
import com.openai.client.okhttp.OpenAIOkHttpClient;
|
||||
import com.openai.models.responses.ResponseCreateParams;
|
||||
|
||||
var first =
|
||||
client
|
||||
.responses()
|
||||
.create(
|
||||
ResponseCreateParams.builder().model("gpt-6-astra").input("Tell me a joke.").build());
|
||||
|
||||
first.output().stream()
|
||||
.flatMap(item -> item.message().stream())
|
||||
.flatMap(message -> message.content().stream())
|
||||
.flatMap(content -> content.outputText().stream())
|
||||
.forEach(text -> System.out.println(text.text()));
|
||||
|
||||
var second =
|
||||
client
|
||||
.responses()
|
||||
.create(
|
||||
ResponseCreateParams.builder()
|
||||
.model("gpt-6-astra")
|
||||
.input("Explain why this is funny.")
|
||||
.previousResponseId(first.id())
|
||||
.build());
|
||||
second.output().stream()
|
||||
.flatMap(item -> item.message().stream())
|
||||
.flatMap(message -> message.content().stream())
|
||||
.flatMap(content -> content.outputText().stream())
|
||||
.forEach(text -> System.out.println(text.text()));
|
||||
```
|
||||
|
||||
```csharp
|
||||
using OpenAI.Responses;
|
||||
#pragma warning disable OPENAI001
|
||||
|
||||
string key = Environment.GetEnvironmentVariable("OPENAI_API_KEY")!;
|
||||
ResponsesClient client = new(key);
|
||||
|
||||
ResponseResult first = await client.CreateResponseAsync(
|
||||
"gpt-6-astra",
|
||||
"Tell me a joke."
|
||||
);
|
||||
Console.WriteLine(first.GetOutputText());
|
||||
|
||||
ResponseResult second = await client.CreateResponseAsync(
|
||||
"gpt-6-astra",
|
||||
"Explain why this is funny.",
|
||||
previousResponseId: first.Id
|
||||
);
|
||||
Console.WriteLine(second.GetOutputText());
|
||||
```
|
||||
|
||||
```ruby
|
||||
require "openai"
|
||||
|
||||
client = OpenAI::Client.new
|
||||
|
||||
first = client.responses.create(
|
||||
model: "gpt-6-astra",
|
||||
input: "Tell me a joke."
|
||||
)
|
||||
puts(first.output_text)
|
||||
|
||||
second = client.responses.create(
|
||||
model: "gpt-6-astra",
|
||||
previous_response_id: first.id,
|
||||
input: "Explain why this is funny."
|
||||
)
|
||||
puts(second.output_text)
|
||||
```
|
||||
|
||||
|
||||
#### `previous_response_id` in WebSocket mode
|
||||
|
||||
If you are using [the Responses API WebSocket mode](https://developers.openai.com/api/docs/guides/websocket-mode), continuation uses the same `previous_response_id` semantics as HTTP mode, but over a persistent socket with repeated `response.create` events.
|
||||
|
||||
The connection-local cache keeps recent previous responses in memory for low-latency continuation. When you use `stream_id`, each lane can retain its latest response; `previous_response_id` still controls lineage, so a new lane can fork from a response on another lane while that response remains available. If an uncached ID cannot be resolved, send a new turn with `previous_response_id` set to `null` and pass full input context.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
##### Data retention for model responses
|
||||
|
||||
|
||||
Response objects are saved for 30 days by default. They can be viewed in the dashboard
|
||||
[logs](https://platform.openai.com/logs?api=responses) page or
|
||||
[retrieved](https://developers.openai.com/api/reference/resources/responses/methods/retrieve) via the API.
|
||||
You can disable this behavior by setting `store` to `false`
|
||||
when creating a Response.
|
||||
|
||||
Conversation objects and items in them are not subject to the 30 day TTL. Any response attached to a conversation will have its items persisted with no 30 day TTL.
|
||||
|
||||
OpenAI does not use data sent via API to train our models without your explicit consent—[learn more](https://developers.openai.com/api/docs/guides/your-data).
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Even when using `previous_response_id`, all previous input tokens for responses in the chain are billed as input tokens in the API.
|
||||
|
||||
|
||||
|
||||
## Managing the context window
|
||||
|
||||
Understanding context windows will help you successfully create threaded conversations and manage state across model interactions.
|
||||
|
||||
The **context window** is the maximum number of tokens that can be used in a single request. This max tokens number includes input, output, and reasoning tokens. To learn your model's context window, see [model details](https://developers.openai.com/api/docs/models).
|
||||
|
||||
### Managing context for text generation
|
||||
|
||||
As your inputs become more complex, or you include more turns in a conversation, you'll need to consider both **output token** and **context window** limits. Model inputs and outputs are metered in [**tokens**](https://help.openai.com/en/articles/4936856-what-are-tokens-and-how-to-count-them), which are parsed from inputs to analyze their content and intent and assembled to render logical outputs. Models have limits on token usage during the lifecycle of a text generation request.
|
||||
|
||||
- **Output tokens** are the tokens generated by a model in response to a prompt. Each model has different [limits for output tokens](https://developers.openai.com/api/docs/models). For example, `gpt-4o-2024-08-06` can generate a maximum of 16,384 output tokens.
|
||||
- A **context window** describes the total tokens that can be used for both input and output tokens (and for some models, [reasoning tokens](https://developers.openai.com/api/docs/guides/reasoning)). Compare the [context window limits](https://developers.openai.com/api/docs/models) of our models. For example, `gpt-4o-2024-08-06` has a total context window of 128k tokens.
|
||||
|
||||
If you create a large prompt—often by including extra context, data, or examples for the model—you run the risk of exceeding the allocated context window for a model, which might result in truncated outputs.
|
||||
|
||||
Use the [tokenizer tool](https://platform.openai.com/tokenizer), built with the [tiktoken library](https://github.com/openai/tiktoken), to see how many tokens are in a particular string of text.
|
||||
|
||||
|
||||
|
||||
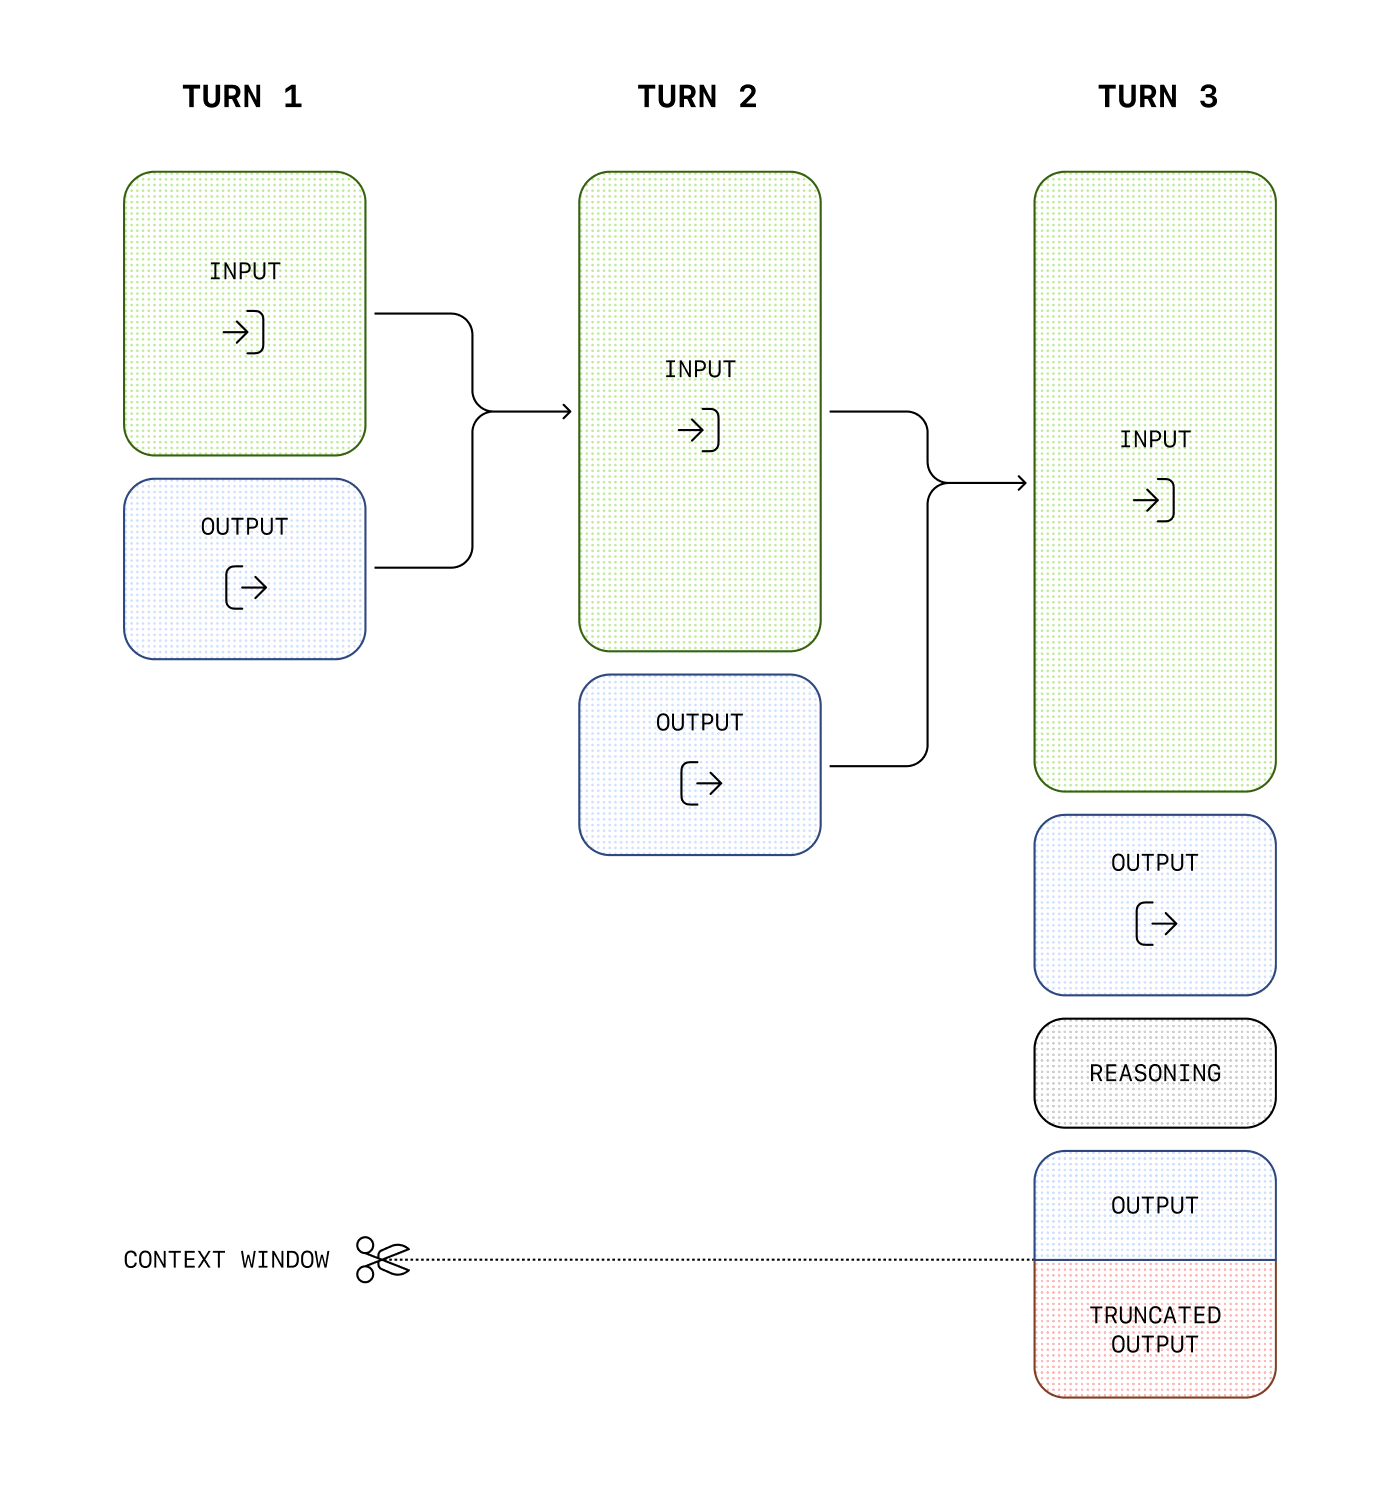
For example, when making an API request to the [Responses API](https://developers.openai.com/api/reference/resources/responses) with a reasoning enabled model, like the [o1 model](https://developers.openai.com/api/docs/guides/reasoning), the following token counts will apply toward the context window total:
|
||||
|
||||
- Input tokens (inputs you include in the `input` array for the [Responses API](https://developers.openai.com/api/reference/resources/responses))
|
||||
- Output tokens (tokens generated in response to your prompt)
|
||||
- Reasoning tokens (used by the model to plan a response)
|
||||
|
||||
|
||||
Tokens generated in excess of the context window limit may be truncated in API responses.
|
||||
|
||||
|
||||
|
||||
You can estimate the number of tokens your messages will use with the [tokenizer tool](https://platform.openai.com/tokenizer).
|
||||
|
||||
<a id="compaction-advanced"></a>
|
||||
|
||||
### Compaction
|
||||
|
||||
Detailed compaction guidance now lives in
|
||||
[Compaction](https://developers.openai.com/api/docs/guides/compaction).
|
||||
|
||||
- For `/responses` with `context_management` and `compact_threshold`, see
|
||||
[Server-side compaction](https://developers.openai.com/api/docs/guides/compaction#server-side-compaction).
|
||||
- For explicit compaction control, see
|
||||
[Standalone compact endpoint](https://developers.openai.com/api/docs/guides/compaction#standalone-compact-endpoint)
|
||||
and the [`/responses/compact` API reference](https://developers.openai.com/api/reference/resources/responses/methods/compact).
|
||||
|
||||
## Next steps
|
||||
|
||||
For more specific examples and use cases, visit the [OpenAI Cookbook](https://developers.openai.com/cookbook), or learn more about using the APIs to extend model capabilities:
|
||||
|
||||
- [Receive JSON responses with Structured Outputs](https://developers.openai.com/api/docs/guides/structured-outputs)
|
||||
- [Extend the models with function calling](https://developers.openai.com/api/docs/guides/function-calling)
|
||||
- [Enable streaming for real-time responses](https://developers.openai.com/api/docs/guides/streaming-responses)
|
||||
- [Build a computer-using agent](https://developers.openai.com/api/docs/guides/tools-computer-use)
|
||||
File diff suppressed because it is too large
Load Diff
Reference in New Issue
Block a user